PNN V4.3 · incl. 1-bit, on CPU & GPU
Maximum Intelligence. Zero Waste.
PNN is a radically efficient neural core that cuts computational waste without sacrificing model quality, delivering proven acceleration across any hardware—from standard CPUs and GPUs to custom silicon.

Measured. Details and conditions on the benchmarks page.
What's new
From 32-bit floats to 1-bit weights
PNN V4.3 runs on NVIDIA GPUs and carries 4-bit and 1-bit weights end to end — model file, training, CPU kernels and chip, bit-exact on an FPGA — and 1-bit PNN puts a vision transformer into 8.9 MB. INT8 stays the default.
- V4.3
Faster on NVIDIA GPUs
PNN kernels for NVIDIA GPUs: a 7B-shaped decoder runs 2.1–3.4× faster than the same model dense at one token on T4, L4 and H100. 1-bit weights end to end — model file, training, CPU kernels and chip, bit-exact on an Artix-7 FPGA.
- 4-bit
4-bit weights, end to end
INT4 in the model file, the CPU runtime and the chip. A dual-mode multiplier computes one 8-bit or two 4-bit products per cycle, formally proven.
- 8.9 MB
1-bit PNN
ViT-B/16 at 71.19 % ImageNet top-1 with sign-only weights — 39× smaller than dense, 2.0× faster than dense int8 on a 4-core CPU.
- 4 CPUs
CPU runtime
Pre-built for x86-64 and ARM64. Faster than tuned dense int8 on Intel, AMD, Arm Neoverse and Apple M1, bit-exact — SLNG: single load, no gather.
- INT8
Quantised without retraining
PNN ViT-B/16 goes to INT8 for 0.32 points of top-1, 49 MB against 346 MB dense FP32. Published on Hugging Face.
- FPGA
Bit-exact on hardware
The generated 4-bit and 1-bit inference cores run on a Xilinx Artix-7: 52,000 outputs equal to the bit-exact model.
- 0.17×
Smaller silicon
Through sky130 place and route, a 1-bit processing element takes 0.17× the area and 0.07× the power of the 8-bit one; 4-bit takes 0.50× and 0.37×.
Offerings
Five ways to put PNN to work
From silicon to ready-made models: buy the chip, license the technology, have us optimize your model, run it on your CPUs or GPUs, or pick one from the store.
- 01Ready-made models
Model store
Pre-converted PNN models, ready to deploy at the precision you need — starting with ViT-B/16 at FP32, BF16, INT8, INT4 and 1-bit.
Go in → - 02Service
Model inference
Run PNN models on available GPUs and CPUs, billed per hour — standard inference, or supermodel inference, distributed and fault-tolerant, for models of any size.
Run → - 03Service
Model optimization
We convert your network to PNN, recover its accuracy by distillation and quantise it to INT8, INT4 or 1-bit — delivered in the standard Hugging Face safetensors format.
Run → - 04Patent + know-how
IP licensing
License PNN for your own products: the patented connectivity, the encoder, CPU kernels and processing-element RTL. Evaluation licence first, then a production licence per design with a royalty per unit.
Talk to us → - 05Silicon
PNN chips
Inference chips that hold a whole model on-chip, from 8-bit down to 1-bit weights — for cameras, sensor heads and battery-powered devices — and training chips that learn in place.
Talk to us →
Key markets
Where the PNN chip goes
Datacenter
Double your AI capacity
Running customers with PNN's smaller memory footprint on PNN kernels with faster execution will virtually double your resources. Spend 10 % on PNN to get 100 % more capacity.
Automotive
Perception at a fraction of the parameters
On real Waymo LiDAR, PNN matches the dense model to every printed digit with 6.7× fewer parameters — headroom for radar, LiDAR and camera stacks on automotive chips.
Robotics
Vision on board, within a robot's power budget
A 1-bit PNN vision transformer runs in 8.9 MB; a chip for it is modelled at 0.6 W — perception that stays on the robot (est).
Edge & IoT
Cameras, sensor heads, battery-powered devices
Whole models in on-chip memory, no DRAM for weights: a 12 mm² chip modelled to run ViT-B/16 ten times faster than a Jetson module (est).
Smartphones & PCs
Smaller models on the processors you already ship
PNN inference runs faster than dense int8 on Arm and x86 CPUs, and 4-bit and 1-bit weights cut the memory a model needs.
Industrial
Fixed models, long lifetimes, low power
A model fixed in silicon — the 1-bit processing element needs 0.17× the area and 0.07× the power of an 8-bit one, in place and route.
(est) = engineering estimate; the other figures are measured.
Datacenter · PNN V4.3
Double your AI capacity
Running customers with PNN's smaller memory footprint on PNN kernels with faster execution will virtually double your resources. Spend 10 % on PNN to get 100 % more capacity.
10 % for compression and the execution layer · 0.9 × 2.2 = 2.0
Faster than dense, token by token, 25 % density
| 8-bit | 4-bit | 1-bit | |
|---|---|---|---|
| 5 CPU types | 2.1–6.5× | as 8-bit | 2.3–6.9× |
| NVIDIA L4 | 3.3–3.7× | 2.5–2.9× | 2.9–4.2× |
| NVIDIA H100 | 1.6–2.6× | 1.2–1.9× | 1.3–1.9× |
Single layers of 7B-class shapes, against dense at the same precision; 1-bit against dense 4-bit (GPUs) or dense INT8 (CPUs). On CPUs 4-bit runs at 8-bit speed with half the weight memory.
- 23×
Smaller
Model file: 1,552 KiB dense FP32 → 115 KiB at 8-bit → 68 KiB at 4-bit (PNN 25 %). 1-bit: 37.4 kB against 1,065 kB in FP32.
- ≤ 0.5 pt
Accurate
What the weight width costs at the same density: 8-bit ±0.0, 4-bit −0.5, 1-bit −0.24 points. How much a density costs is measured per model.
- 2.1–3.4×
Faster
A whole 7B-shaped decoder at 25 % density, one token, against the same model dense on NVIDIA T4, L4 and H100.
License the PNN compression and execution layer
- PNN compression: transcoding of any model with linear layers, distillation, 8-, 4- and 1-bit weights, density per layer.
- PNN model format: safetensors + config.json, the Hugging Face layout.
- PNN execution layer: the PNN kernel library for x86 and Arm CPUs and NVIDIA GPUs, from C, Python and PyTorch.
Start with the V4.3 evaluation package, then a pilot on your models and your hardware: accuracy, size and speed per density and weight width, and the capacity gain they give.
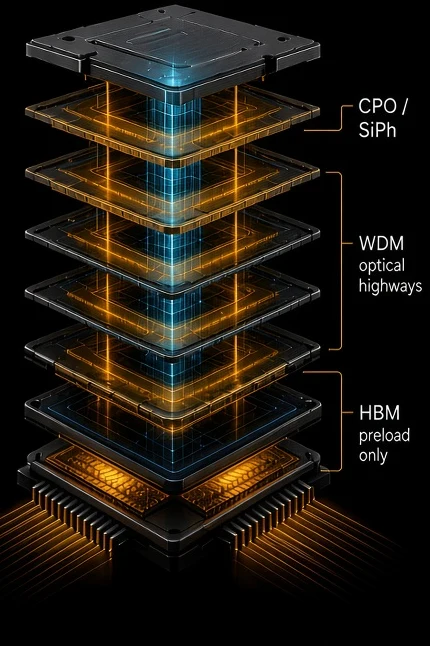
Next · concept study
PNN LightStack
A trillion-parameter model in a single rack, at one token per clock: a billion tokens per second.
Read the concept →The capacity gain is an estimate built on measured speed-ups, not a guarantee. It depends on the model, the density it tolerates and the share of token-by-token serving; with many tokens per call dense GPU kernels are fast, and the PNN library then runs those layers on the dense path. At 50 % density the gains are smaller.
About us
A seasoned leadership team
We bring together the inventor of the technology, AI research, two company exits and standards-level reach across the industry — with a US presence where chips get designed — guided by a board of advisors from silicon IP, automotive, robotics, semiconductor analysis and IP law.
Dr. Jorg Nonnenmacher
CEO
Inventor of PNN. Founded, ran and sold two companies to Nasdaq-listed acquirers — the last of them AI that finds ads on TV.
Dr. Arnd Kohrs
Head of AI
PhD in prediction and collaborative filtering. Seasoned lead for customers and partners, from startups to industry heavyweights (IBM).
Thierry Fautier
Managing Director, US
Emmy Award winner for video AI. Former Chairman of the Ultra HD Forum, where he assembled the industry around a single format.
Isa Best, AI
VP Marketing
Our AI VP Marketing, based in San Francisco: leads PNN's marketing.
Board of advisors
Jos Burger
Chairman
Former CEO of Ultimaker, the Dutch 3D-printing company he led from 2015 to 2021. Earlier CEO of Palet Kabelcom. Chairs the supervisory board of E-magy.
Christophe Frey
Silicon IP
Former General Manager of Arm France, which grew fourfold under his lead. Joined Arm with its acquisition of SOISIC after 12 years at STMicroelectronics.
Erik Huggers
Robotics
Senior Advisor at EQT and board member of Hexagon, the industrial measurement and robotics group. Former CEO of Vevo; executive roles at Intel, Microsoft, BBC and Verizon.
Bruno Paucard
Automotive
Founder & CEO of Silicon Mobility (acquired by Intel in 2024), which delivered control solutions — chips, software, system — for electric and Software-Defined Vehicles.
Amar Bouali
Formal verification
INRIA. Formerly CTO of Esterel Technologies, then at Ansys and Synopsys. Formal validation of system-on-chip and DSP designs; author of XEVE, the Esterel verification environment.
Tristan Gerra
Semiconductor analyst
Managing Director and Senior Analyst, Semiconductors, at Robert W. Baird since 2004, covering about 20 semiconductor companies. Earlier at SoundView and Prudential.
BlueshiftIP
IP counsel
Patent firm in Cambridge, Massachusetts, for software and computer technology. Co-founded by Robert Plotkin, an MIT-educated computer scientist and patent attorney.